How we build conversational fleet analytics on AI agents

AuthorAndrew M., VP of Data and Solutions
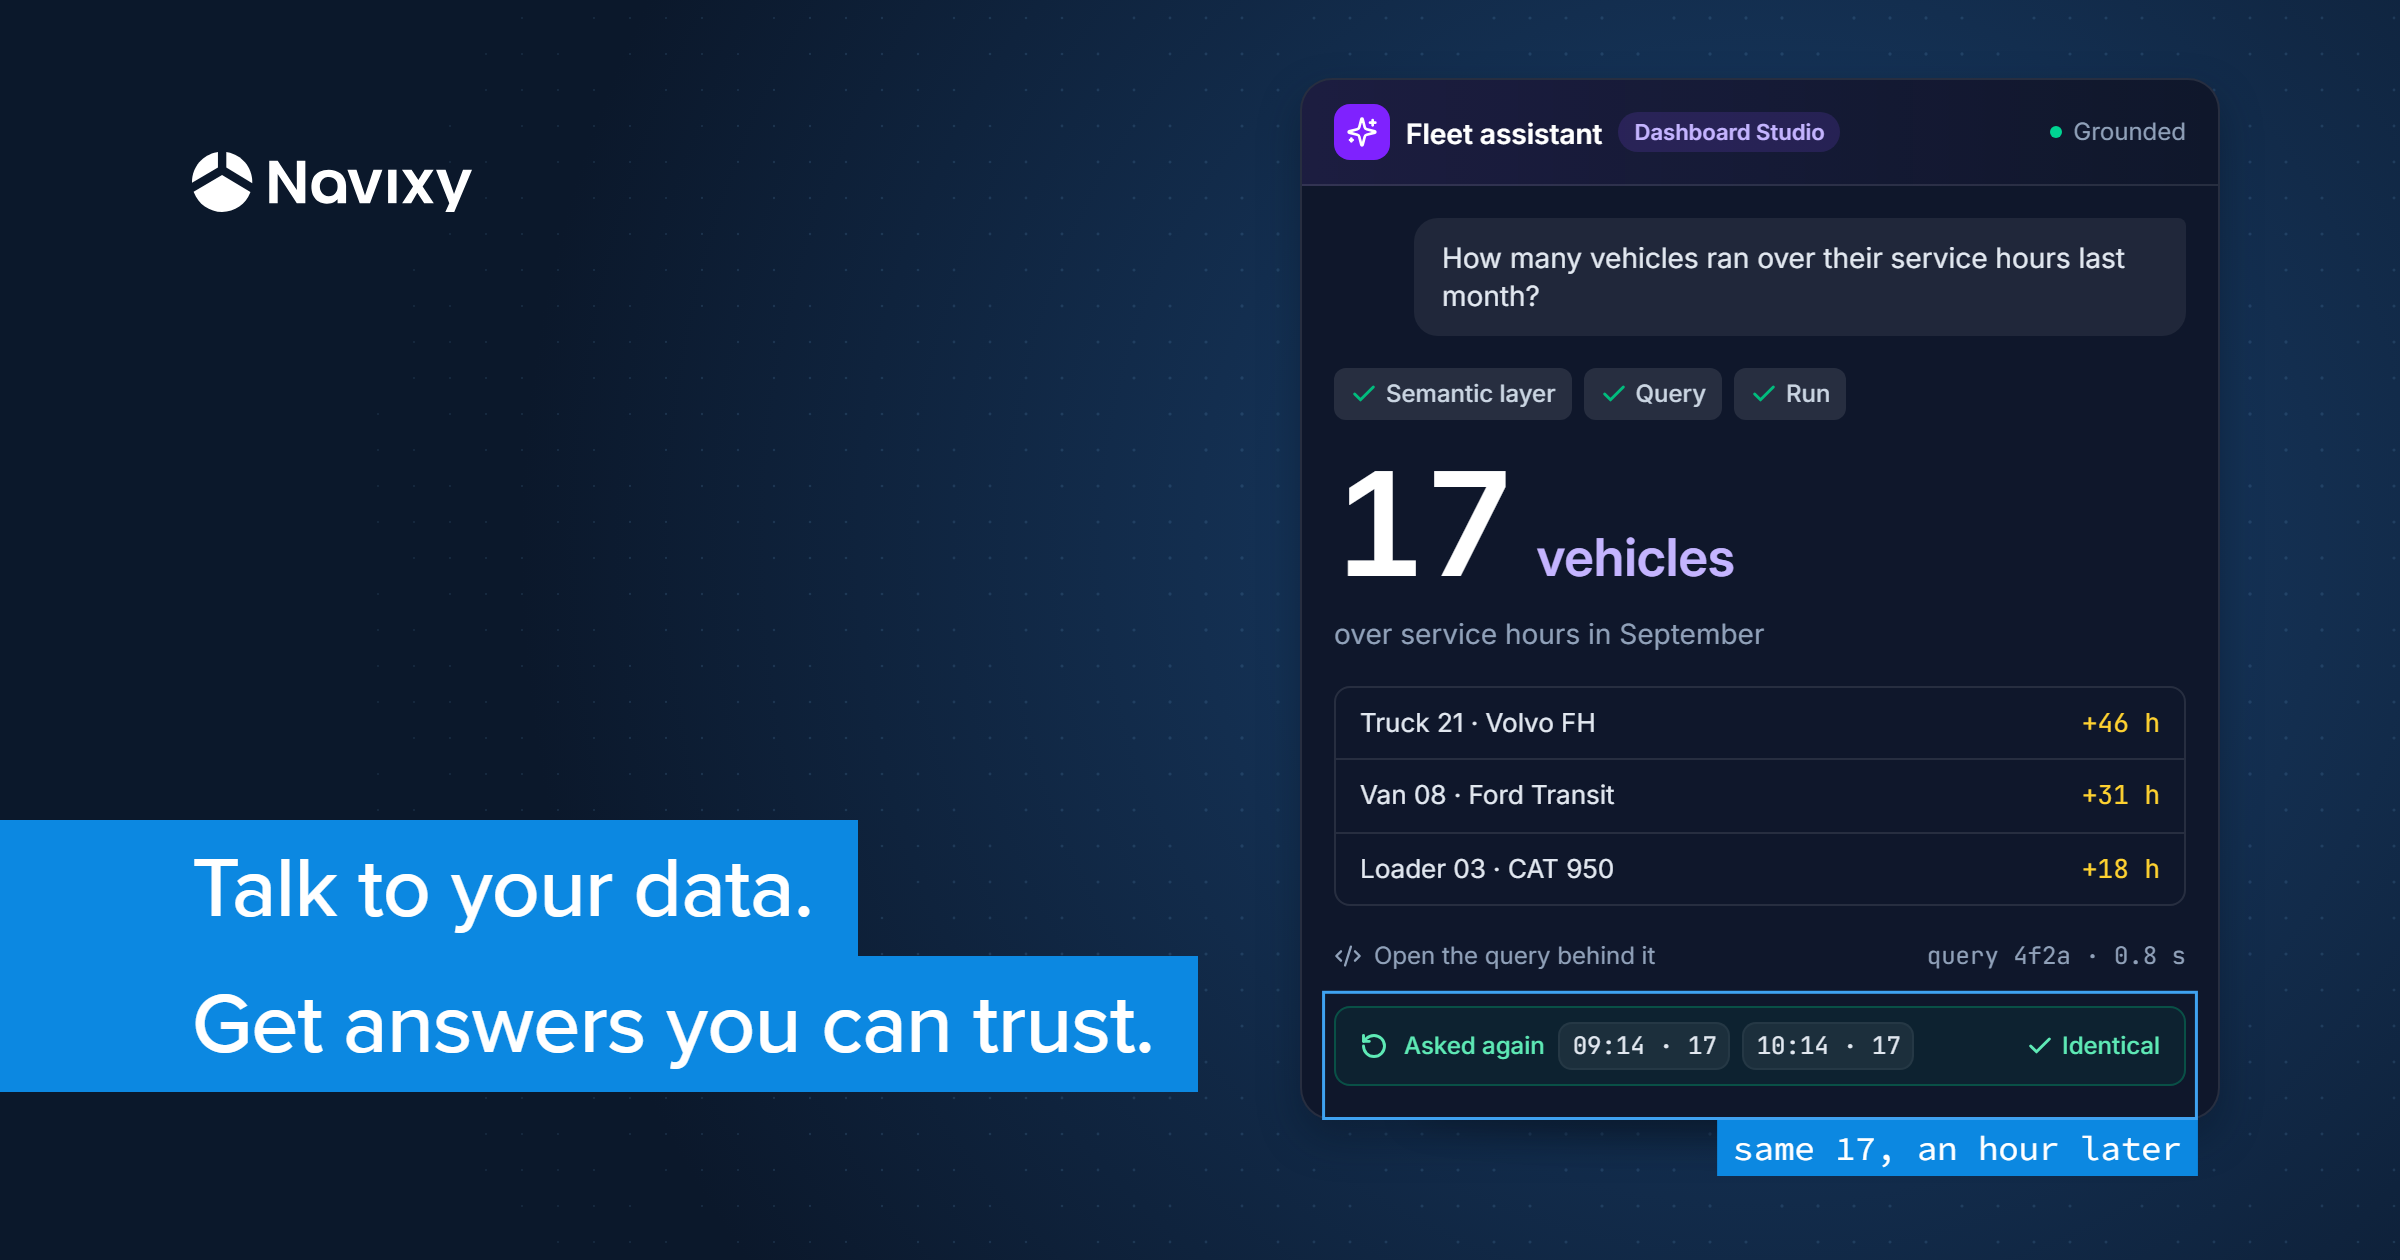
Conversational analytics is the next step past dashboards toward understanding how a fleet actually operates — and let's admit it, most dashboards never get studied in depth. With an AI agent built into your analytics system, a user can ask a question in plain words, get the information they need right away, and dig into the details themselves.
Navixy is moving in this direction. The AI agent built into our BI tool Dashboard Studio already builds dashboards from natural-language requests. But a text-based assistant running on a large language model (LLM) isn't always accurate, so our main goal is making sure every answer is correct and current.
Trustworthy conversational analytics is first of all an architecture problem, not a chatbot one. We keep improving our agent, and we want to share how we do it.
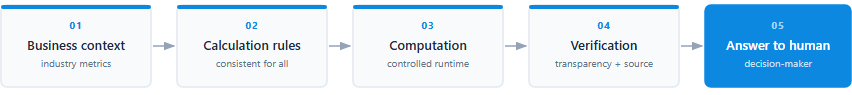
At Navixy, our approach to conversational analytics rests on five layers, each one removing a specific cause of errors in AI answers:
1. Context: teach the fleet AI your telematics vocabulary
Language models understand natural language. But they don't know how a given term is defined in your platform or in a customer's business processes — and the cost of that gap is measurable. Industry research consistently shows that routing queries through a predefined semantic metrics layer cuts agent error rates by up to two-thirds. That layer bridges the gap between universal language and each company's own context.
The goal isn't to "connect the LLM to a telemetry database." It's to teach the system what this data means to each specific customer.
Fleet monitoring is full of terms that only look unambiguous. A few examples:
- What "online" means: did the tracker send any message in the last hour, or did it report a valid GPS fix?
- Does "idle time" count a period when the engine is running but speed is zero? And what threshold must be crossed?
- Is a "trip" defined by ignition on and off, or by actual movement? See the Documentation article on how to set and adjust trip parameters inside the platform.
When two teams use the same word for two different calculations, the system can confidently produce a wrong answer. In a multi-customer solution, the definitions also differ from one client to the next.
2. Execution: let a controlled runtime do the math
AI models are excellent at generating text. But they aren't deterministic calculation engines. Ask the same question about a numerical metric twice and you might get two different answers. This becomes a problem when those metrics — mileage, engine hours, or fuel consumption — are the ones customers use in reports, comparisons, or billing.
So don't ask the AI model to "calculate" something. Better to start by asking it to formulate the calculation logic and get the user's confirmation, then have the actual computation run by an algorithm or script in a controlled execution environment. That's where the quality of such operations is substantially higher.
A reliable pattern looks like this:
Understand → Plan → Generate query/code → Execute → Inspect → Explain.
Running code also makes the answer transparent and reproducible. The technical team can review the code behind an answer, verify it, and reproduce the result — rather than just taking the model's word for it.
3. Validation: start narrow, expand slowly
AI assistants handle specific questions well. But open the door to "ask anything," and the answers tend to be inapplicable rather than useful.
Take fleet analytics in Dashboard Studio and compare two queries.
| "How many devices were online yesterday?" | "What's wrong with the fleet?" |
|---|---|
| ✓ clear rules ✓ checkable answer ✓ comparable against the platform's own data |
✗ no rules defined ✗ system builds its own interpretation ✗ answer is hard to verify |
A more reliable approach is to start with specific scenarios, benchmarked against reference examples, that customers ask most often. When evaluating results from an AI agent, four criteria need to hold at once:
- Accuracy: is the answer correct?
- Reproducibility: does it hold up on repeat?
- Grounding: does it trace back to real data?
- Scope adherence: did the system stay inside what it can reliably answer?
At Navixy, we expand the scope only when the system meets all four. We grow the analytics system's capabilities gradually — never ahead of the trust built around it.
4. Transparency: show how the answer was reached
A correct answer and a trusted answer are two different problems. Transparency closes the gap between them and keeps your support team out of every "why does the number say that?" ticket.
A simple test: can a non-technical user — a dispatcher or an operations manager, not an engineer — understand where a metric value came from in 20 to 30 seconds? If not, the trust problem isn't solved yet. Everyone working with a conversational analytics system should be able to see, quickly enough, how and on what data an answer rests.
When people regularly see the logic behind calculations, they build a better model of what the system can and can't do, and start asking more precise questions. That creates a continuous feedback loop.
In the end, transparency becomes part of the product. It's also required for AI governance and accountability — questions enterprise customers will always ask.
5. Governance: match autonomy to the cost of being wrong
An AI assistant answers every question with the same confidence, but the cost of being wrong isn't the same for every question. The stricter the control needs to be, the higher the cost of an error.
- Low risk — summaries, comparisons, open-ended exploration of trips and utilization. These tasks can run largely on autopilot. A slightly off number gets corrected on the next question.
- Medium risk — recommendations, anomaly interpretation (an unusual fuel drop or a route deviation), operational decisions. These deserve more scrutiny, because someone is going to act on the result.
- High risk — safety, compliance, financial exposure, critical maintenance. Real guardrails are required here. A wrong answer isn't an inconvenience, it's an incident. The AI must never guess: any uncertainty should immediately hand the question to a human expert.
A sound default is the Pareto split: for roughly 80% of routine tasks, users can review the output themselves, while the 20% of high-stakes decisions call for stricter controls.
Conversational analytics you can trust
The Navixy team is building the architecture of its conversational analytics system not around a polished dialogue — but around trust. First, the system gets business context. Then it translates that into verified calculation rules that govern every computation. Computations run in a controlled, transparent way. Every result is checked and immediately shown with the data it rests on. Only then does the answer reach the human making a decision.
The "chat with your data" experience users notice is just the surface. The real advantage comes when the system can not only answer, but explain, check its data, and bring in a human where attention is needed. That is what customers keep using — because it helps them make decisions with confidence.
Ready to put these five layers to work? Talk to us about building fleet AI solutions your customers can trust.
On this page