> For the complete documentation index, see [llms.txt](https://navixy.com/docs/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://navixy.com/docs/analytics/dashboard-studio/writing-sql-queries.md).
# Writing SQL queries
Write PostgreSQL queries optimized for Dashboard Studio visualizations. Learn data access patterns, layer selection, and performance best practices
Dashboard Studio uses SQL to retrieve data from IoT Query schemas. You write SQL in two contexts: panel editors, where statements power visualizations, and the standalone SQL Editor for data exploration. This page explains how to write effective SQL for both contexts, with emphasis on visualization requirements since they have specific structural constraints.
### Where SQL is used
Dashboard Studio provides two SQL environments for different purposes. Understanding when to use each helps you work more efficiently.
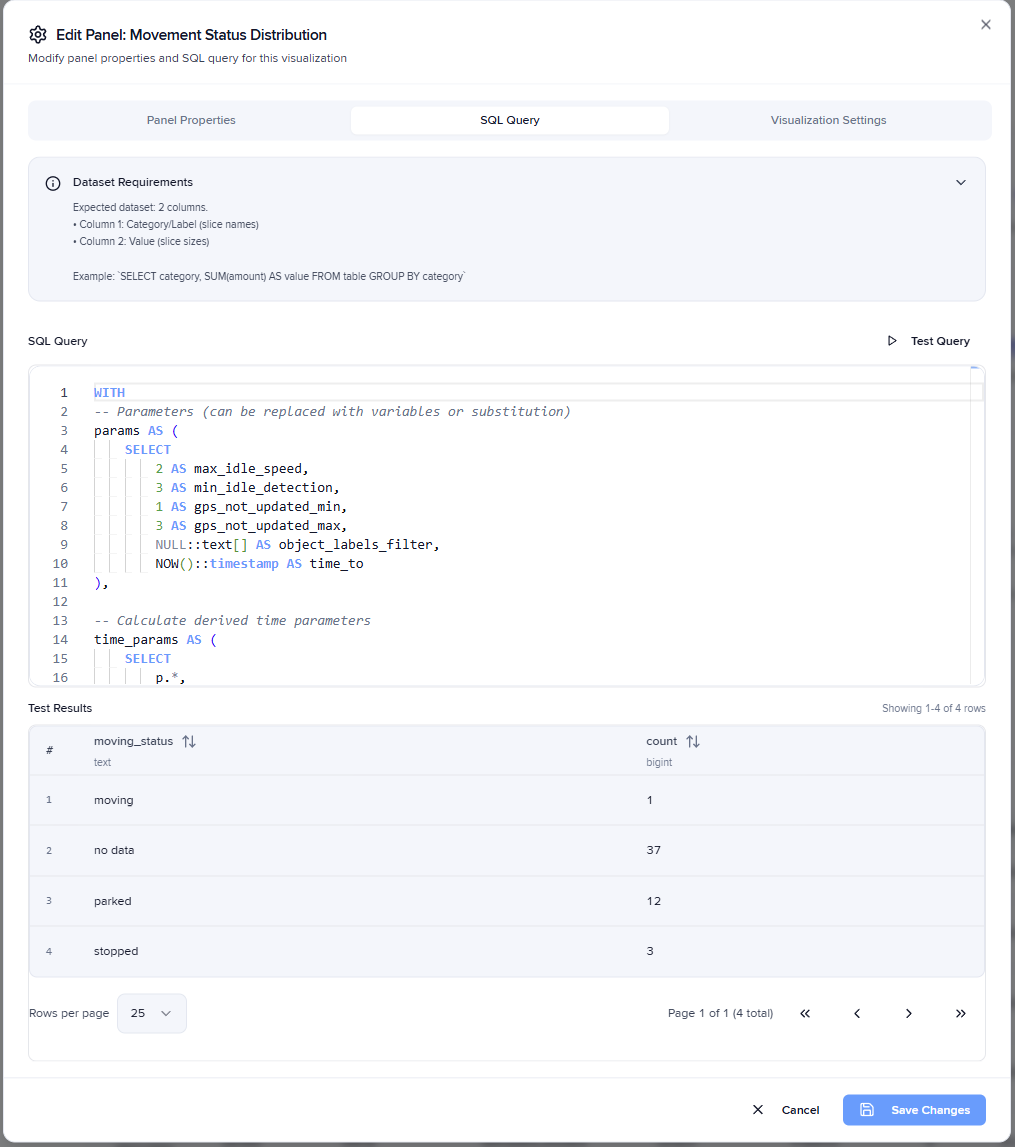
[**Visualization queries**](#how-to-write-sql-for-visualizations) power individual panels in reports. You write these statements in the panel editor's **SQL Query** tab. Each panel runs one statement that must return data in a specific structure matching the visualization type. These statements execute when reports load or refresh, so performance matters for user experience. Visualization SQL cannot modify data; all statements run as read-only SELECT operations against IoT Query schemas.
**Reports** use the same visualization SQL approach as dashboard panels. A report runs one query that powers three views simultaneously: the data table, chart, and location map. The statement must return all columns needed across all three components, so include coordinate, time, and metric columns together in a single SELECT.
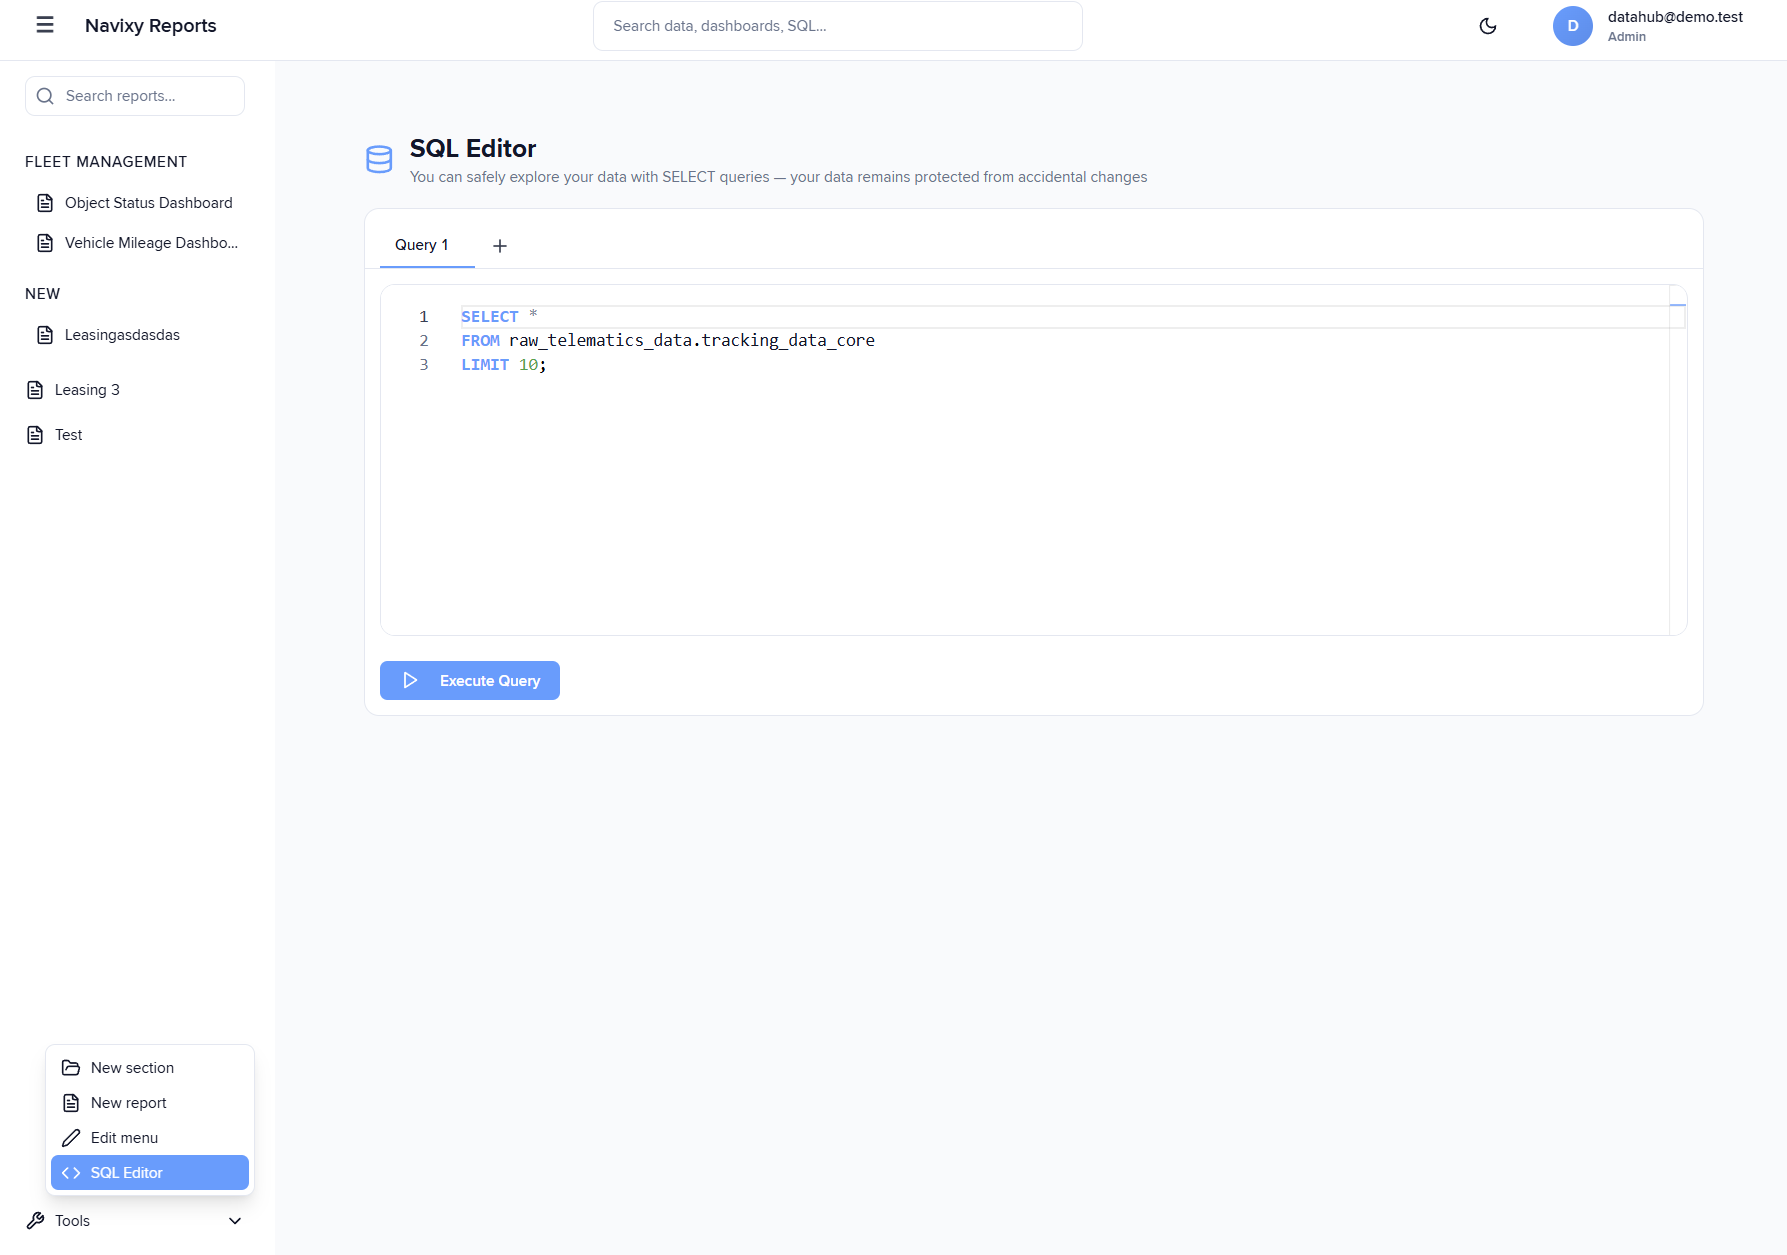
[**SQL Editor**](#how-to-use-the-sql-editor) supports data exploration and export. Access the SQL Editor from the left sidebar under Tools. Write any SELECT statement to examine data structure, validate assumptions, or export results as CSV. The SQL Editor shows full result tables with column sorting and provides execution metrics. Use this for testing logic before adding SQL to visualization panels, or for ad-hoc data extraction that doesn't need visualization.
{% hint style="info" %}
**The key difference**: visualization SQL must match exact column structures, while SQL Editor statements can return any result format. Test complex logic in SQL Editor first, then adapt it for visualizations.
{% endhint %}
### How to write SQL for visualizations
Visualization SQL must return specific column counts and data types. Dashboard Studio cannot render a bar chart from three columns or a stat tile from text data. Check the Dataset Requirements section in the SQL Query tab to see exactly what your chosen visualization expects before writing the statement. The table below contains supported visualization types:
| Visualization | Query requirement | Example |
| ------------------------ | ------------------------------ | ----------------------------------------------------------------- |
| [Stat tile](#stat-tiles) | Single numeric value | `SELECT COUNT(*) FROM schema.table` |
| [Bar chart](#bar-charts) | Two columns: category, value | `SELECT column1, COUNT(*) FROM schema.table GROUP BY column1` |
| [Pie chart](#pie-charts) | Two columns: label, value | `SELECT category, SUM(value) FROM schema.table GROUP BY category` |
| [Table](#tables) | Any columns | `SELECT column1, column2, column3 FROM schema.table` |
| [Text](#text-panels) | No query required | Markdown, HTML, or plain text |
| [Maps](#maps) | Latitude and longitude columns | `SELECT latitude, longitude FROM schema.table` |
Stat tiles
Stat tiles display single numeric values. Statements must return exactly one row with one numeric column:
{% code title="Total trips in current month" overflow="wrap" %}
```sql
SELECT COUNT(*) as value
FROM processed_common_data.trips
WHERE trip_start_time >= DATE_TRUNC('month', CURRENT_DATE);
```
{% endcode %}
{% code title="Total distance traveled (km)" overflow="wrap" %}
```sql
SELECT ROUND(SUM(trip_distance_meters) / 1000.0, 1) as value
FROM processed_common_data.trips
WHERE trip_start_time >= CURRENT_DATE - INTERVAL '7 days';
```
{% endcode %}
The column name doesn't matter, only that the result is a single numeric value. Dashboard Studio displays this value with formatting you configure in Visualization Settings.
Bar charts
Bar charts require exactly two columns: category (text or date) and value (numeric). The first column becomes the X-axis, the second becomes bar heights:
{% code title="Trips per object" overflow="wrap" %}
```sql
WITH device_owner AS (
SELECT DISTINCT ON (o.device_id) o.device_id, o.object_label
FROM raw_business_data.objects o
WHERE o.is_deleted IS NOT TRUE
ORDER BY o.device_id, o.object_id
)
SELECT
d.object_label as category,
COUNT(*) as value
FROM processed_common_data.trips t
LEFT JOIN device_owner d ON d.device_id = t.device_id
WHERE t.trip_start_time >= DATE_TRUNC('month', CURRENT_DATE)
GROUP BY d.object_label
ORDER BY value DESC;
```
{% endcode %}
Group by a text column. `raw_business_data.vehicles.vehicle_type` holds an integer code rather than a name, so grouping by it labels the bars `1`, `2`, `3`.
The `device_owner` block at the top is not optional whenever you join object labels onto trips or events. See [How to join object labels](#how-to-join-object-labels).
{% code title="Daily trip counts" overflow="wrap" %}
```sql
SELECT
DATE_TRUNC('day', trip_start_time)::date as category,
COUNT(*) as value
FROM processed_common_data.trips
WHERE trip_start_time >= CURRENT_DATE - INTERVAL '30 days'
GROUP BY DATE_TRUNC('day', trip_start_time)
ORDER BY category;
```
{% endcode %}
Use `ORDER BY` to control the bar sequence. Sort by value for ranked comparisons or by category for time-series progressions.
Pie charts
Pie charts require exactly two columns: label (text) and value (numeric). The first column becomes slice labels, the second determines slice sizes:
{% code title="Trips by starting zone" %}
```sql
SELECT
start_zone as label,
COUNT(*) as value
FROM processed_common_data.trips
WHERE trip_start_time >= DATE_TRUNC('month', CURRENT_DATE)
AND start_zone IS NOT NULL
GROUP BY start_zone
ORDER BY value DESC
LIMIT 10;
```
{% endcode %}
Add LIMIT clauses for categories with many values. Pie charts with 20+ slices become unreadable; limit to top 10-15 categories.
Tables
Tables accept any number of columns with any data types. Select the columns you want to display:
{% code title="Recent trip details" %}
```sql
SELECT
device_id,
trip_start_time,
trip_end_time,
ROUND(trip_distance_meters / 1000.0, 1) as distance_km,
ROUND(trip_duration_seconds / 60.0) as duration_minutes,
max_speed
FROM processed_common_data.trips
WHERE trip_start_time >= CURRENT_DATE - INTERVAL '7 days'
ORDER BY trip_start_time DESC
LIMIT 100;
```
{% endcode %}
Column names become table headers. Use aliases with spaces for readable headers: `ROUND(trip_distance_meters / 1000.0, 1) as "Distance (km)"`.
Text panels
Text panels display Markdown, HTML, or plain text content. They don't run a SQL query.
On the **Content** tab, select an option under **Content Mode**:
* **Markdown** (default) supports formatting such as headings and links.
* **HTML** renders raw markup.
* **Plain Text** displays the content exactly as you entered it and doesn't interpret any markup.
Use text panels for section headers, instructions, or context alongside your data visualizations.
Maps
Map panels plot one marker per row. Statements must return a latitude column and a longitude column:
{% code title="Latest vehicle positions" overflow="wrap" %}
```sql
WITH device_owner AS (
SELECT DISTINCT ON (o.device_id) o.device_id, o.object_label
FROM raw_business_data.objects o
WHERE o.is_deleted IS NOT TRUE
ORDER BY o.device_id, o.object_id
)
SELECT DISTINCT ON (t.device_id)
d.object_label,
t.latitude / 1e7 AS latitude,
t.longitude / 1e7 AS longitude
FROM raw_telematics_data.tracking_data_core t
LEFT JOIN device_owner d ON d.device_id = t.device_id
WHERE t.device_time >= NOW() - INTERVAL '24 hours'
AND t.latitude <> 0 AND t.longitude <> 0
ORDER BY t.device_id, t.device_time DESC;
```
{% endcode %}
`DISTINCT ON` with the matching `ORDER BY` keeps one row per device, the newest. Without it, the query plots every historical point the device ever sent.
Dashboard Studio detects coordinate columns automatically when they use common names such as `latitude`, `lat`, or `gps_lat` for latitude and `longitude`, `lon`, or `lng` for longitude. If your columns use different names, select them manually in Visualization Settings.
Coordinates must be in decimal degrees. Where a table stores them as scaled integers, divide by `1e7` as shown above. Any other columns the statement returns appear in the marker popup.
Report queries follow the same structural rules as visualization queries in dashboard panels. Because a single statement powers the data table, chart, and location map together, you may need to combine columns that would be written as separate panel queries in a dashboard. For example, a bar chart panel query returning two columns is not sufficient for a report that also needs GPS coordinates for the location map. Include all required columns for every component in one statement. The core filtering and JOIN logic remains the same as in panel queries; only the SELECT clause needs to be wider.
### How to write SQL for reports
A report runs one SQL query that powers three components simultaneously: the data table, chart, and location map. Unlike dashboard panels, where each panel has its own focused query, a report query must return all columns needed across every component in a single SELECT statement.
#### Column requirements per component
Each report component has specific column requirements. Your query must satisfy all components you have enabled.
| Component | Required columns | Notes |
| ------------ | ----------------------------------------------------------------- | ------------------------------------------------ |
| Data table | Any columns | All returned columns appear as table columns |
| Chart | At least one time or category column, at least one numeric column | Axis columns are selected in the chart settings |
| Location map | Latitude and longitude as decimal degrees | Dashboard Studio auto-detects coordinate columns |
Because the data table accepts any columns, it imposes no additional constraints. The chart and location map drive most of the structural decisions.
#### Combining components in one query
A query that returns only the columns needed for a chart (two columns: category and value) cannot also power a location map. You must include all required columns together.
The following example returns columns for all three components: a time column and numeric column for the chart, coordinate columns for the location map, and additional attributes that appear in the data table.
```sql
WITH device_owner AS (
SELECT DISTINCT ON (o.device_id) o.device_id, o.object_label
FROM raw_business_data.objects o
WHERE o.is_deleted IS NOT TRUE
ORDER BY o.device_id, o.object_id
)
SELECT
t.device_id,
d.object_label,
t.device_time,
t.latitude::float / 10000000 AS latitude,
t.longitude::float / 10000000 AS longitude,
t.speed::float / 100 AS speed
FROM raw_telematics_data.tracking_data_core t
LEFT JOIN device_owner d ON d.device_id = t.device_id
WHERE t.device_time >= NOW() - INTERVAL '24 hours'
ORDER BY t.device_time DESC
LIMIT 1000
```
In this query, `device_time` and `speed` serve the chart, `latitude` and `longitude` serve the location map, and all columns appear in the data table.
{% hint style="info" %}
The raw telematics tables store coordinates and speed as scaled integers. Coordinates are divided by 10,000,000 (10⁷) to convert to decimal degrees, and speed is divided by 100 (10²) to convert to km/h. Apply these conversions in any query that reads from `raw_telematics_data` tables.
{% endhint %}
#### Adapting dashboard panel queries for reports
Any panel query from a dashboard is a valid starting point for a report. The adjustment needed depends on which components you want to enable.
If the panel query is already a table visualization returning multiple columns, it may already include everything needed. Add coordinate columns if the location map is required.
If the panel query is a bar chart or stat tile query returning aggregated results, it likely lacks the row-level detail needed for the data table and location map. In that case, remove the aggregation and work from the underlying Raw data layer or Transformation layer tables instead.
[SQL Recipe Book](/docs/analytics/example-queries.md) contains ready-to-use query examples for common fleet analyses. Recipes from the book can be adapted for reports by adding coordinate columns where the location map is needed. The core WHERE and JOIN logic transfers directly; adjust only the SELECT clause to cover all required components.
### How to use global variables
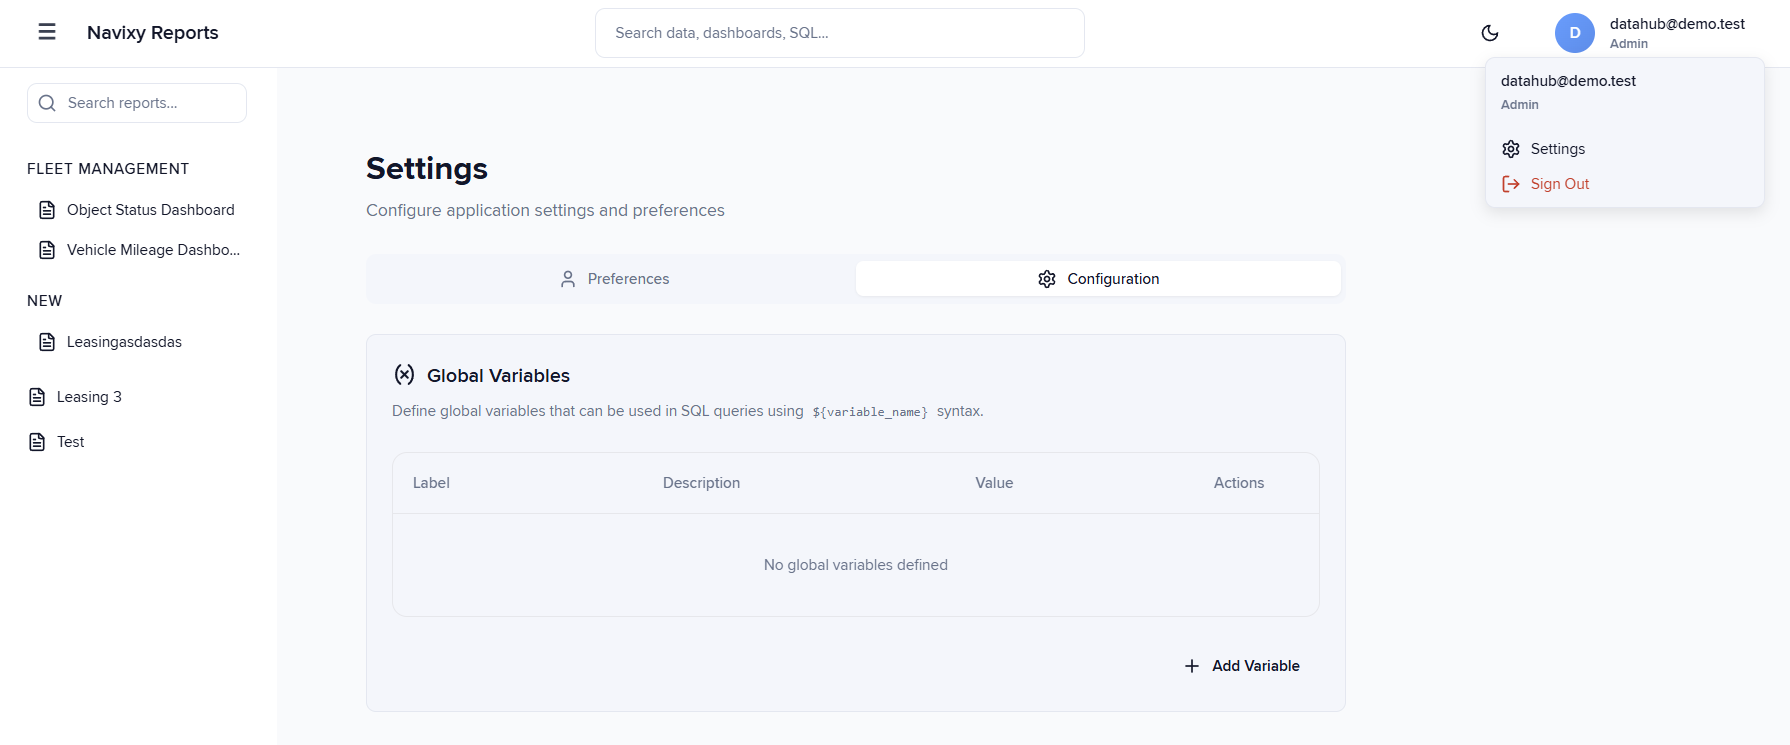
Global variables provide reusable values across multiple SQL statements. Define variables in **Settings > Configuration > Global Variables**, then reference them using `${variable_name}` syntax.
Define variables for values that change periodically but remain consistent across multiple panels: analysis date ranges, vehicle type filters, or threshold values. When these values change, update the variable definition once instead of editing individual SQL statements.
{% code title="Using date range variables" %}
```sql
SELECT
DATE_TRUNC('day', trip_start_time)::date as category,
COUNT(*) as value
FROM processed_common_data.trips
WHERE trip_start_time >= '${analysis_start_date}'::date
AND trip_start_time < '${analysis_end_date}'::date
GROUP BY DATE_TRUNC('day', trip_start_time)
ORDER BY category;
```
{% endcode %}
Variables store text values. Cast them to appropriate types in SQL: `'${variable_name}'::date` for dates, `'${variable_name}'::integer` for numbers.
For statement-specific parameters that change frequently, you can use CTE parameter blocks at the start:
```sql
WITH params AS (
SELECT
300 as min_idle_seconds,
10 as max_idle_speed_kmh,
'${analysis_start_date}'::date as date_from,
'${analysis_end_date}'::date as date_to
)
SELECT
e.device_id,
COUNT(*) as idle_count,
ROUND(SUM(e.duration_sec) / 60.0) as total_idle_minutes
FROM processed_common_data.rule_based_driver_events e
CROSS JOIN params p
WHERE e.event_type = 'idling_soft'
AND e.device_time >= p.date_from
AND e.device_time < p.date_to
AND e.speed_kmh <= p.max_idle_speed_kmh
AND e.duration_sec >= p.min_idle_seconds
GROUP BY e.device_id
ORDER BY total_idle_minutes DESC;
```
This pattern combines global variables (date ranges) with statement-specific parameters (thresholds), keeping all adjustable values at the top for easy maintenance.
### How to join object labels
`raw_business_data.objects.device_id` is not unique. One device can carry several object records, because a device reassigned between objects leaves the earlier rows behind. Fact tables such as `processed_common_data.trips` key on `device_id` alone, so a plain join to `objects` multiplies every fact row by the number of matching object records. Counts and sums then come out too high, with no error to tell you.
Filtering on `is_deleted` isn't enough on its own, because more than one record can survive that filter. Pick one row per device first, then join that:
{% code title="The object-label join" %}
```sql
WITH device_owner AS (
SELECT DISTINCT ON (o.device_id) o.device_id, o.object_id, o.object_label
FROM raw_business_data.objects o
WHERE o.is_deleted IS NOT TRUE
ORDER BY o.device_id, o.object_id
)
SELECT d.object_label, COUNT(*) AS trips
FROM processed_common_data.trips t
LEFT JOIN device_owner d ON d.device_id = t.device_id
WHERE t.trip_start_time >= CURRENT_DATE - INTERVAL '30 days'
GROUP BY d.object_label;
```
{% endcode %}
Use `LEFT JOIN` rather than an inner join, so that a device with no surviving object record still appears rather than dropping out of the result.
`processed_common_data.rule_based_driver_events` is the exception. It already carries `object_id` and `object_label`, and its coordinates are in degrees, so it needs neither this join nor the `/1e7` conversion.
### How to access IoT Query schemas
IoT Query organizes data in Raw data, Transformation, and Insight layers. The Raw data and Transformation layers each hold two PostgreSQL schemas, and you reference a table by its schema name rather than by the layer. Choosing the right layer saves time and keeps SQL clear. For complete schema details, see the [IoT Query Schema Overview](/docs/analytics/iot-query/schema-overview.md).
**Raw data layer** holds what devices and the Navixy platform recorded, in two schemas. `raw_telematics_data` holds tracking, input, and state data: `raw_telematics_data.tracking_data_core` stores every GPS position with timestamps, coordinates, and sensor readings. `raw_business_data` holds business entities such as `raw_business_data.objects`, `raw_business_data.vehicles`, and `raw_business_data.zones`. Use the Raw data layer for point-level analysis, for raw sensor values, and for the labels and attributes you join onto processed data.
**Transformation layer** holds processed entities in two schemas. `processed_common_data` holds the transformations Navixy maintains, which are available without configuration: `trips`, `sensors_data_by_hours`, `rule_based_driver_events`, and `input_change_events`. `processed_custom_data` holds the transformations you build yourself in Transformation Builder. Use the Transformation layer for most visualization needs, because it provides analysis-ready structures. See [Common transformations](/docs/analytics/iot-query/schema-overview/transformation-layer/common-transformations.md) for each table's columns.
**Insight layer** offers pre-aggregated metrics and dimensional models for complex analytics. Use it for fleet-wide statistics or multi-dimensional analysis that would otherwise need complex joins against Transformation layer tables.
{% hint style="warning" %}
The layer names Bronze, Silver, and Gold describe the medallion architecture the layers follow. They aren't schema names, and `silver.trips` isn't a table you can query. Use the schema names above.
{% endhint %}
Reference tables using `schema.table` format: `processed_common_data.trips`, not just `trips`. Include date range filters in WHERE clauses to limit data scanned:
{% code title="Always filter by time ranges" %}
```sql
SELECT device_id, COUNT(*) as trip_count
FROM processed_common_data.trips
WHERE trip_start_time >= CURRENT_DATE - INTERVAL '30 days'
GROUP BY device_id;
```
{% endcode %}
Most SQL statements filter by device, time range, or both. Add these filters early in WHERE clauses to reduce data volume processed.
### Units of measurement in query results
IoT Query stores every measurement in one fixed unit, and Dashboard Studio renders whatever the query returns. It doesn't convert values into the measurement system set on the Navixy account, the way the pre-built Dashboards app does. Two people with different account settings see the same numbers on the same panel.
Each column's unit is documented in the [IoT Query Schema Overview](/docs/analytics/iot-query/schema-overview.md), and many columns name it directly. `trip_distance_meters` holds meters, `avg_speed` and `max_speed` hold km/h, and `altitude_start` and `altitude_end` hold meters above sea level. Check the column before you label a panel.
Convert in the query when your readers work in other units, and name the unit in the column alias so the panel labels itself correctly:
{% code title="Returning distance in miles rather than meters" %}
```sql
SELECT device_id,
ROUND(SUM(trip_distance_meters) / 1609.344, 1) as "Distance (mi)"
FROM processed_common_data.trips
WHERE trip_start_time >= CURRENT_DATE - INTERVAL '7 days'
GROUP BY device_id;
```
{% endcode %}
Divide meters by 1,609.344 for miles, km/h by 1.609344 for mph, and meters by 0.3048 for feet.
### How to use the SQL Editor
Access SQL Editor from the left sidebar under Tools. Use it for three main purposes: testing logic before adding to panels, exploring data schemas to understand available columns, and exporting data that doesn't need visualization.
The SQL Editor supports multiple tabs for different statements. Write SQL in tabs, execute with the "Execute Query" button, and view results in the table below. Results show execution metrics (execution time, rows returned) and support column sorting for quick data examination.
Export results as CSV using the "Export CSV" button. This works for ad-hoc reports or data extracts for external analysis. The SQL Editor has no result row limit, unlike visualization SQL which should return focused datasets.
Test visualization SQL in the SQL Editor before adding to panels. Write the statement, verify it returns expected columns and data types, then copy it to the panel editor's SQL Query tab. This workflow catches structural issues before you configure visualization settings.
Exploration pattern for new data:
{% code expandable="true" %}
```sql
-- 1. Examine table structure
SELECT * FROM processed_common_data.trips LIMIT 10;
-- 2. Check date range coverage
SELECT
MIN(trip_start_time) as earliest,
MAX(trip_start_time) as latest,
COUNT(*) as total_trips
FROM processed_common_data.trips;
-- 3. Test filtering logic
SELECT
device_id,
trip_start_time,
trip_distance_meters
FROM processed_common_data.trips
WHERE trip_start_time >= '2024-01-01'
AND device_id = 12345
ORDER BY trip_start_time;
-- 4. Adapt for visualization (2 columns for bar chart)
SELECT
DATE_TRUNC('day', trip_start_time)::date as day,
COUNT(*) as trips
FROM processed_common_data.trips
WHERE trip_start_time >= '2024-01-01'
AND device_id = 12345
GROUP BY DATE_TRUNC('day', trip_start_time)
ORDER BY day;
```
{% endcode %}
### Common SQL patterns
Most visualization SQL follows similar patterns. Copy these structures and adjust filters, columns, and aggregations for your specific needs.
Time-series counts for tracking trends
```sql
SELECT
DATE_TRUNC('hour', trip_start_time) as time_bucket,
COUNT(*) as event_count
FROM processed_common_data.trips
WHERE trip_start_time >= CURRENT_DATE - INTERVAL '24 hours'
GROUP BY DATE_TRUNC('hour', trip_start_time)
ORDER BY time_bucket;
```
Category rankings for comparing groups
```sql
SELECT
category_column,
COUNT(*) as count
FROM schema.table
WHERE filter_conditions
GROUP BY category_column
ORDER BY count DESC
LIMIT 15;
```
Metric calculations for aggregated statistics
```sql
SELECT
ROUND(SUM(trip_distance_meters) / 1000.0, 1) as total_distance_km,
ROUND(AVG(trip_duration_seconds) / 60.0) as avg_duration_minutes,
COUNT(*) as trip_count
FROM processed_common_data.trips
WHERE trip_start_time >= DATE_TRUNC('week', CURRENT_DATE);
```
Filtered summaries with multiple conditions
```sql
SELECT
device_id,
COUNT(*) as trips,
ROUND(SUM(trip_distance_meters) / 1000.0, 1) as total_km
FROM processed_common_data.trips
WHERE trip_start_time >= '${period_start}'::date
AND trip_start_time < '${period_end}'::date
AND trip_distance_meters >= 5000
AND trip_duration_seconds >= 600
GROUP BY device_id
HAVING COUNT(*) >= 5
ORDER BY total_km DESC;
```
### What to do when SQL fails
Execution failures fall into three categories: structural mismatches with visualization requirements, SQL syntax errors, or filters that return no data.
#### **Column structure mismatches**
Occur when results don't match visualization expectations. If you selected a bar chart but your SQL returns three columns, Dashboard Studio cannot render it. Check Dataset Requirements in the SQL Query tab. The bar chart needs exactly two columns (category, value), so adjust your SELECT clause:
```sql
-- Wrong: three columns
SELECT device_id, trip_start_time, COUNT(*) FROM processed_common_data.trips GROUP BY device_id, trip_start_time;
-- Correct: two columns
SELECT device_id, COUNT(*) as trips FROM processed_common_data.trips GROUP BY device_id;
```
#### **SQL syntax errors**
Show specific error messages. Common issues include missing schema prefixes (`trips` instead of `processed_common_data.trips`), typos in column names, or incorrect date casting. Test statements in SQL Editor to see detailed error messages with line numbers.
#### **Empty results**
Despite successful execution indicate filters exclude all data. Test the SQL without WHERE clauses in SQL Editor to verify the table contains data, then add filters incrementally to identify which condition excludes your expected results.
#### Performance issues
If statements execute slowly or timeout, add date range filters to WHERE clauses. Operations scanning entire tables process millions of rows unnecessarily:
```sql
-- Slow: no date filter
SELECT device_id, COUNT(*) FROM processed_common_data.trips GROUP BY device_id;
-- Fast: date range filter
SELECT device_id, COUNT(*)
FROM processed_common_data.trips
WHERE trip_start_time >= CURRENT_DATE - INTERVAL '30 days'
GROUP BY device_id;
```
For additional performance guidance, see [How to access IoT Query schemas](#how-to-access-iot-query-schemas) for best practices on filtering and schema selection.
### Where to find SQL examples
The [SQL Recipe Book](/docs/analytics/example-queries.md) provides complete examples for common telematic analyses. These recipes demonstrate patterns for trip analysis, zone visit calculations, idle detection, and fleet metrics. Each recipe includes the complete SQL statement, explanation of logic, and sample results.
Adapt Recipe Book examples for visualizations by adjusting the SELECT clause to match visualization requirements. A recipe that returns detailed trip records can become a bar chart by adding GROUP BY and COUNT aggregation. A statement calculating per-vehicle metrics can become a stat tile by adding SUM across all vehicles.
You just need to:
1. Copy examples from [Recipe Book](/docs/analytics/example-queries.md) to the Dashboard Studio'sEditor.
2. Test with your actual data.
3. Verify results, then modify the SELECT clause for your target visualization.
The core WHERE and JOIN logic remains the same; you adjust only the output structure.
For schema details, see the [IoT Query Schema Overview](/docs/analytics/iot-query/schema-overview.md). This reference explains available tables, column definitions, and relationships between Raw data, Transformation, and Insight layers.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation dynamically by asking a question.
Perform an HTTP GET request on the current page URL with the `ask` query parameter, and the optional `goal` query parameter:
```
GET https://navixy.com/docs/analytics/dashboard-studio/writing-sql-queries.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is optional and describes the broader end goal you are ultimately trying to accomplish on behalf of the user. GitBook uses it to tailor the answer towards what is most useful for that goal.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.